Table of Contents
Summarize and analyze this article with
Chat GPT
Perplexity
Grok
Google AI
Claude
An AI decline is still an adverse action
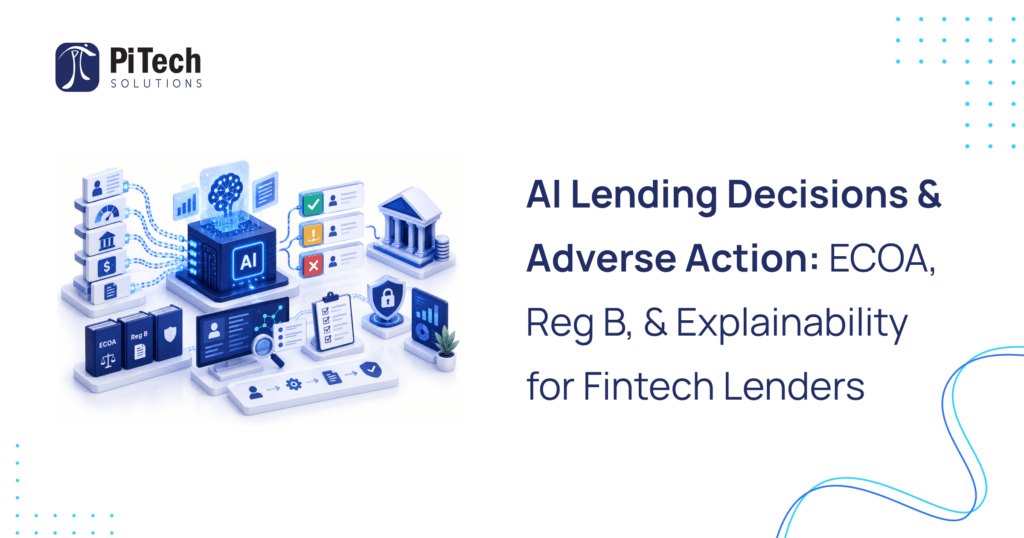
A model that declines a credit application, or approves it on worse terms, has taken an adverse action, and the Equal Credit Opportunity Act and its implementing Regulation B require the lender to give the applicant a statement of the specific principal reasons. That obligation does not soften because the decision came from a complex model. Regulatory guidance has been explicit that a creditor cannot rely on the opacity of its model to avoid giving accurate, specific reasons, and that generic checklists of sample reasons can fall short when they do not reflect the actual basis for the decision. For a fintech lender, this makes explainability and fair-lending testing part of the credit product, not an afterthought.
This guide explains what an adverse-action-ready AI lending stack needs and how to build it. It is educational and not legal advice.
What an adverse-action-ready AI lending stack needs
| Component | What it covers | Evidence produced |
|---|---|---|
| Accurate reason codes | Specific principal reasons that reflect the actual basis for the decision | Adverse-action notices that map to the model’s real drivers |
| Per-decision explainability | The factors that drove each individual decision, not just global importance | Traceable, decision-level explanations |
| Fair-lending testing | Disparate-impact testing and search for less-discriminatory alternatives | Documented fair-lending analysis and mitigations |
| Adverse-action workflow | Reg B timing and content for notices | Compliant, auditable notices and delivery records |
| Model risk governance | Validation, monitoring, and drift control | Validation reports and monitoring logs |
| Data governance | Provenance and quality of the features used | Documented, defensible feature lineage |
Fair lending is a design constraint, not a report
Disparate-impact risk is not removed by leaving protected characteristics out of the model, because proxies remain. A defensible program tests model outcomes for disparate impact across protected classes and, where impact is found, searches for and documents less-discriminatory alternatives that still meet the business need. That testing belongs in development and in ongoing monitoring, not only in an annual review, because models drift and populations change. Building the testing pipeline into the model lifecycle is what lets a lender answer a fair-lending question with evidence rather than assertion.
Then audit the review path itself, including the identity checks bolted onto the front of it. On 11 August 2026 the California Privacy Protection Agency Board issued a decision requiring a data broker to pay 116,490 dollars, alleging among other things that it required Californians to provide the last four digits of their Social Security number before they could opt out of the sale of their personal information, which the agency treated as a data-minimization violation. The identity proofing in front of a review queue is regulated too.
Where PiTech fits
How to choose a partner
- Reason codes that reflect reality : Explainability that produces accurate specific reasons, not a fixed checklist.
- Fair-lending testing in the lifecycle : Disparate-impact and less-discriminatory-alternative testing in development and monitoring.
- Model risk discipline : Validation, monitoring, and documentation that survive an exam.
- Works with compliance : Owns the data and engineering, not the legal determination.
The bottom line
An AI decline is an adverse action, and the law requires accurate, specific reasons regardless of model complexity. Build reason codes that reflect the real decision, test for disparate impact across the lifecycle, and keep the validation and monitoring evidence an exam will ask for.
Frequently Asked Questions (FAQs)
Does AI lending have to comply with adverse-action rules?
Yes. When a lender declines an application or offers less favorable terms based on a model, it has taken an adverse action, and the Equal Credit Opportunity Act and Regulation B require a statement of the specific principal reasons. This applies whether the decision comes from a simple scorecard or a complex machine-learning model. The obligation is to give accurate, specific reasons that reflect the actual basis for the decision, not generic language. Fintech lenders using AI underwriting therefore need the ability to explain individual decisions well enough to produce compliant adverse-action notices, which is why explainability is a core requirement rather than an optional feature.
Can a fintech avoid reason codes because its model is too complex?
No. Regulatory guidance has been explicit that a creditor cannot rely on the complexity or opacity of its model to escape the obligation to give specific, accurate adverse-action reasons. If a model is too complex to explain, that is a reason to reconsider using it for credit decisions, not a defense. Guidance has also cautioned that relying on a fixed checklist of sample reasons can fall short when the listed reasons do not reflect the actual basis for the decision. The practical answer is per-decision explainability that produces reason codes mapping to the real drivers of each decision, which is an engineering requirement you build in from the start.
What is a specific, principal reason for adverse action?
It is an accurate statement of the main factors that actually drove the adverse decision for that applicant, for example a high debt-to-income ratio or limited credit history, rather than vague or boilerplate language. Regulation B requires that adverse-action notices disclose the specific principal reasons, and guidance has stressed that the reasons must reflect the actual basis of the decision. For AI models, this means the explainability method must identify, per decision, which factors were principal, and the reason codes must translate those into language an applicant can understand. Reasons that do not correspond to what the model actually did are a compliance problem.
How do we test AI lending models for fair lending?
Test model outcomes for disparate impact across protected classes, and where you find impact, search for and document less-discriminatory alternatives that still meet the business objective. Leaving protected characteristics out of the model does not remove the risk, because other features can act as proxies, so the test is on outcomes, not inputs. This analysis belongs in development and in ongoing monitoring rather than only in a periodic review, because models drift and applicant populations change. The output is documented evidence: the disparate-impact analysis, any alternatives considered, and the rationale for the model in use, which is what lets you answer a fair-lending inquiry with facts.
Does excluding race and gender make a model fair?
What model risk governance do fintech lenders need?
Fintech lenders, especially those partnering with banks, are expected to apply model risk management discipline: independent validation of the model before use, ongoing monitoring for performance and drift, clear documentation of data, assumptions, and limitations, and governance over changes. Bank partners operate under supervisory model-risk expectations and will push those onto their fintech partners, so a lender that cannot produce validation and monitoring evidence creates risk for the partnership. Building model risk governance in from the start, rather than assembling it under exam pressure, is what keeps an AI lending program both compliant and fundable through bank relationships.
How does model explainability support compliance?
Explainability provides the per-decision insight needed to produce accurate adverse-action reasons and to support fair-lending analysis. For adverse action, it identifies which factors were principal in an individual decline so the notice reflects the real basis of the decision. For fair lending, it helps diagnose why a model produces particular outcomes and where proxies may be driving disparate impact. Explainability also supports model validation and monitoring by making model behavior inspectable. In short, explainability is the connective tissue between a complex model and the specific, accurate disclosures and analyses that credit law requires, which is why it is engineered in rather than bolted on.
Are the compliance rules the same for a fintech and a bank?
The core credit laws, ECOA and Regulation B, apply to credit decisions regardless of whether the lender is a bank or a fintech. Where fintechs partner with banks, the bank’s supervisory expectations, including model risk management and fair-lending oversight, flow through to the fintech via the partnership. Some supervisory frameworks apply directly to banks and reach fintechs through those relationships rather than as direct obligations. The safe assumption for a fintech lender is that it must meet bank-grade expectations on adverse action, fair lending, and model risk, both to comply with the credit laws and to sustain the bank partnerships its model often depends on.
How do I choose an AI lending compliance partner?
Look for a partner that produces explainability capable of generating accurate specific reason codes rather than a fixed checklist, builds disparate-impact and less-discriminatory-alternative testing into development and monitoring, and delivers the model validation and monitoring evidence an exam requires. The partner should own the data and engineering while working alongside your compliance and legal teams, who own the legal determinations. Check for process maturity and ISO certifications as signals of disciplined delivery, and ask how they keep reason codes and fair-lending testing current as models drift. Avoid anyone who treats explainability or fair lending as a one-time report rather than a lifecycle capability.
Does PiTech help with AI lending compliance?
Yes. PiTech Solutions builds the data, explainability, and testing that make AI lending defensible: feature governance and lineage, per-decision explainability that feeds accurate reason codes, disparate-impact and less-discriminatory-alternative testing, and the model validation and monitoring examiners expect. It works alongside the lender’s compliance and legal teams, owning the data and engineering that turn a fair-lending policy into evidence. Delivery runs under CMMI Level 3 and ISO 27001, 9001, and 42001 certifications. For fintech lenders that need bank-grade explainability and fair-lending rigor at a mid-market price, PiTech is a specialist partner, complementing rather than replacing legal counsel.